5 Best Open Source Tavily Alternatives
A curated collection of the 5 best open source and self-hosted alternatives to Tavily in 2026.
Looking for a free, privacy-friendly, or self-hosted replacement for Tavily in 2026? The top open-source alternative is Firecrawl — API for AI agents to search, scrape, crawl, and interact with the live web, returning clean Markdown, structured JSON, or screenshots from any page..
Other highly rated open-source Tavily alternatives include Crawl4AI, Swirl Search and OpenSERP.
API for AI agents to search, scrape, crawl, and interact with the live web, returning clean Markdown, structured JSON, or screenshots from any page.
API for AI agents to search, scrape, crawl, and interact with the live web, returning clean Markdown, structured JSON, or screenshots from any page.

Open-source LLM-friendly web crawler & scraper
Crawl4AI is an open-source, LLM-friendly web crawler and scraper designed to extract and structure web content efficiently for AI applications. It provides developers with a flexible toolkit to crawl websites, handle anti-bot challenges, and generate structured data outputs. - LLM-Friendly Output: Generates structured markdown, JSON, or raw HTML for seamless AI integration - Adaptive Crawling: Dynamically adjusts crawling strategies based on website complexity - Anti-Bot Bypass: Advanced techniques to handle modern anti-scraping measures - Multi-Mode Crawling: Simple, deep, and adaptive crawling modes for different use cases - C4A-Script Support: Custom scripting language for precise content extraction - Self-Hosting Capabilities: Deployable on your own infrastructure for full data control - Browser Automation: Built-in browser support for JavaScript-heavy websites - PDF Parsing: Extract text from PDF documents during crawling - Proxy & Session Management: Rotate IPs and manage multiple sessions - Markdown Generation: Automatically converts crawled content to clean markdown format - Cache Modes: Optimize performance with different caching strategies - Local File Support: Crawl local files and raw HTML alongside web content Crawl4AI is open-source and can be self-hosted using Docker or installed directly on your server. The project provides comprehensive documentation for deployment, configuration, and scaling. It supports various deployment options including cloud providers, on-premise servers, and local development environments. The crawler is built with Python and provides both CLI and API interfaces for integration into existing workflows.
Private knowledge layer for enterprise AI search
SWIRL is the private knowledge layer for enterprise AI, delivering canonical, organization-approved answers pulled live from your existing systems—no copying, no secondary indexes, and no vector databases required. - Live Federated Search: One query searches across all enterprise sources (M365, SharePoint, Salesforce, iManage, Box, Snowflake, databases, and 150+ others) in real time. - Canonical Answer Selection: Teams pin and endorse the authoritative version of any document or policy, ensuring AI agents and humans receive the approved answer—not the model’s best guess. - Permission-Aware Access: Respects existing security models and permissions in each source system, eliminating the need for data duplication or governance overhead. - Agentic Enablement via MCP: Headless API-first architecture with a first-class MCP server, enabling safe AI agent integration without data leaving your tenant. - Semantic Deduplication & Ranking: Clusters versions of the same document, scores them by source authority, naming, and recency, and elects the canonical version with explainability. - Token Efficiency: Avoids unnecessary data copying and vector database indexing, reducing costs and complexity. - Enterprise-Ready Security: Supports SSO, OAuth2, and OIDC with no bulk data movement or secondary storage. - Plug-and-Play Deployment: Free tier available with Apache 2.0 license; enterprise deployments supported via private cloud or on-premises. - Open Source Core: The SWIRL search engine is open source (Apache 2.0) and available on GitHub. - Self-Hosting Options: Deployable in your own cloud workspace (e.g., AWS, GCP, Azure) or on-premises with one-click installation. - MCP Integration: Native support for Model Context Protocol (MCP) enables seamless integration with AI agents like Claude, Copilot, and custom solutions. - Connectors & Plugins: Extensive library of pre-built connectors for enterprise systems (M365, SharePoint, Salesforce, iManage, Box, databases, etc.). - Scalability: Designed for high-performance federated search across distributed enterprise environments. SWIRL eliminates the risks of AI adoption by ensuring your data stays in place, your security model remains intact, and your teams and agents always receive the approved, canonical answer.
Free self-hosted SERP API for 6 search engines
OpenSERP is a free, open-source SERP API that provides structured search results from six major search engines without requiring API keys or per-query fees. It simplifies web search, competitor tracking, and AI-powered insights for developers and businesses. - Multi-Engine Support: Query Google, Bing, Yandex, Baidu, DuckDuckGo, and Ecosia through a single API. - Structured JSON Output: Consistent, normalized results with titles, URLs, snippets, ranks, and SERP features like AI summaries and answer boxes. - Self-Hosting: MIT-licensed, free to self-host with no vendor lock-in or API key requirements. - AI Monitoring: Track rankings, competitor performance, and generate AI-driven insights for SEO and competitive intelligence. - Page Extraction: Extract content from search results for research, RAG, or data pipelines. - Managed API: Cloud-based option with usage history, billing, and AI reports for teams preferring a hosted solution. - SDKs & Integrations: Compatible with Go, Docker, n8n, and MCP server for seamless integration. - Free Tier: 60 free credits for cloud API users, with founder discounts and no limits on self-hosted usage. OpenSERP is built with Go and Docker, making it easy to deploy on any infrastructure. The self-hosted version requires no account or API key, while the managed cloud API offers additional features like usage tracking and AI reports. The project is MIT-licensed and production-ready for both individual developers and enterprise teams.

Real-time Google Search API with structured data
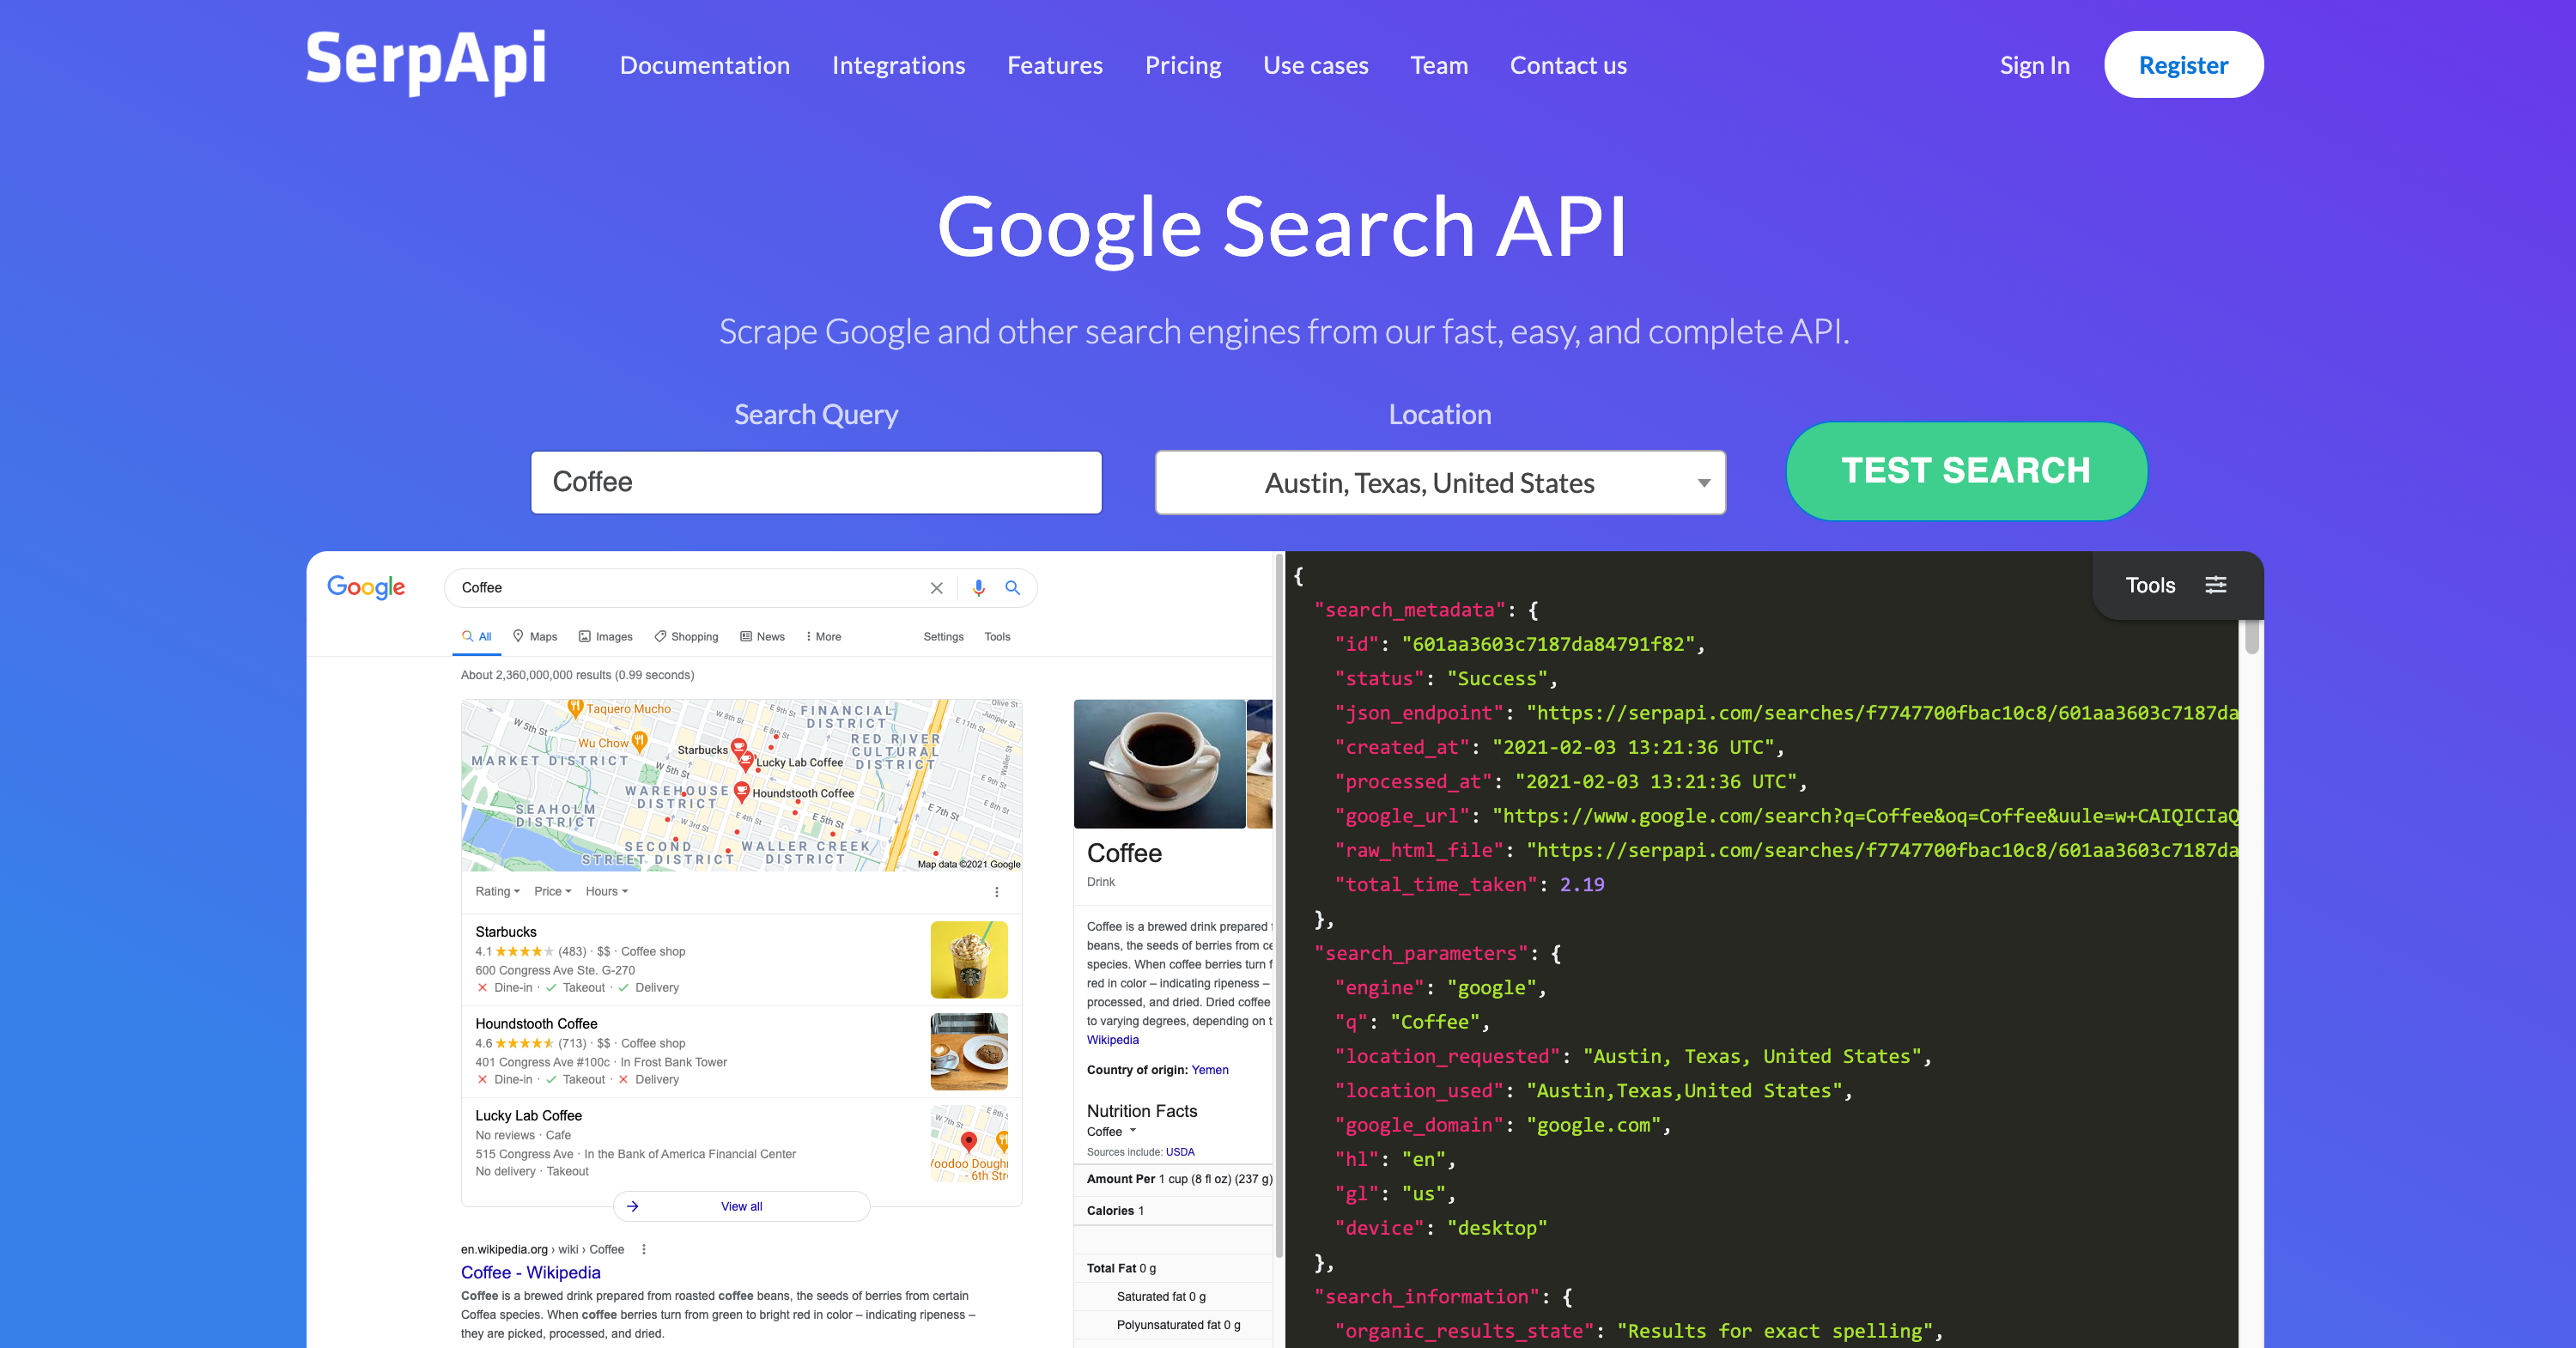
SerpApi is a real-time API service that simplifies access to search engine results, particularly Google searches. It eliminates the complexity of managing proxies, solving captchas, and parsing unstructured data, delivering clean, structured JSON responses ready for integration. - Real-time Search API: Access live Google search results instantly - Multi-Engine Support: Works with Google, Bing, DuckDuckGo, Amazon, eBay, and more - Structured Data Parsing: Automatically formats results into clean JSON - Captcha Handling: Manages CAPTCHAs automatically - Proxy Management: Handles IP rotation and proxy infrastructure - AI Mode Integration: Supports Google's AI Mode and AI Overview APIs - Comprehensive Coverage: Offers 50+ specialized APIs for different search types - Enterprise Solutions: Provides custom plans for business needs - Developer Tools: Includes SDKs for multiple programming languages SerpApi is a fully managed cloud service with no self-hosting option. The service handles all infrastructure requirements including proxy rotation, CAPTCHA solving, and data parsing. Developers interact with the API through simple HTTP requests to SerpApi's endpoints. The company maintains servers globally to ensure fast response times worldwide. While the core service isn't open source, SerpApi provides official SDKs for Ruby, Python, PHP, Java, Node.js, and Go to simplify integration.
About Tavily
Tavily is the real-time search engine designed for AI agents and Retrieval-Augmented Generation (RAG) workflows. It provides fast, secure APIs to access and extract structured content from the web, enabling AI systems to reason over fresh, factual data without hallucinations.
Key Features of Tavily
- Real-time Web Search: Fast and relevant web results with low latency (180ms p50) for AI agents.
- Content Extraction: Clean and structured content extraction for LLMs, ensuring high-quality input.
- Research Agent: In-depth web research capabilities for complex queries and deep reasoning.
- Website Crawling: Extract content from entire websites with built-in safeguards.
- URL Mapping: Discover and map URLs across any website for comprehensive data retrieval.
- Security & Privacy: Built-in layers to block PII leakage, prompt injection, and malicious sources.
- Scalability: Handles thousands of web queries per second with intelligent caching and indexing.
- Benchmark Performance: Ranked #1 on SealQA and SimpleQA benchmarks for search-augmented reasoning.
Tech / Self-Hosting
Tavily is a cloud-based service with no self-hosting option. It integrates seamlessly with leading LLM providers (OpenAI, Anthropic, Groq) and supports drop-in API usage for AI agents and RAG workflows. The service is backed by a 99.99% uptime SLA and powers mission-critical systems for enterprises.