
Beam
Run inference, sandboxes, and task queues on serverless GPUs with instant autoscaling and OpenAI-compatible APIs. Pay only for active compute time.
Beam is an open-source alternative to:




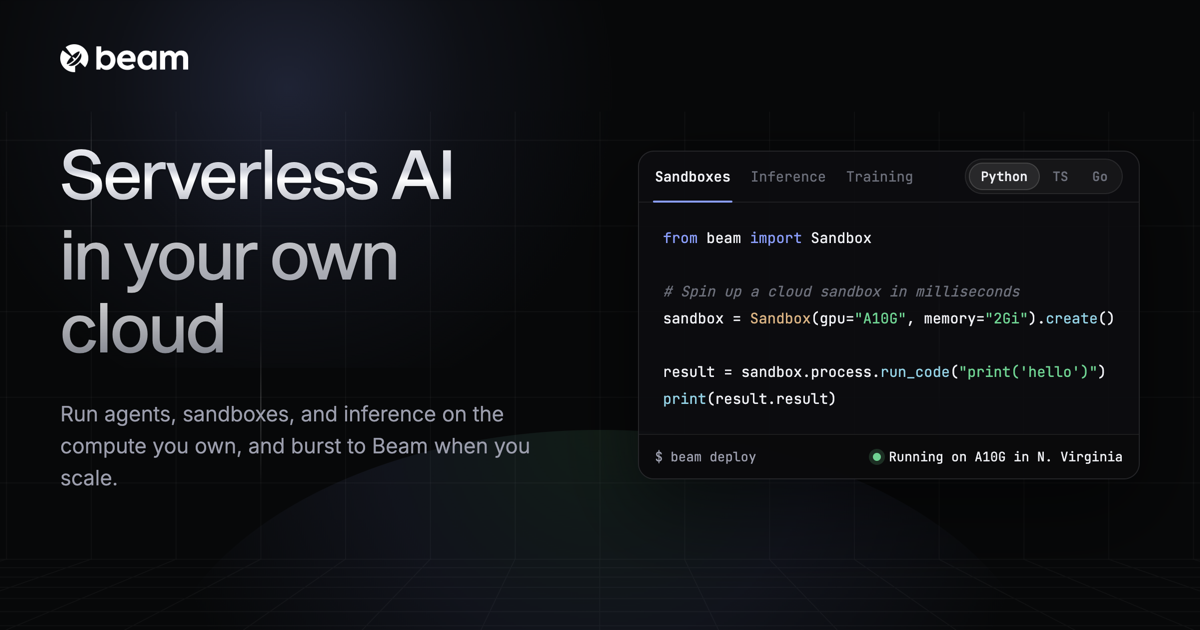
Beam is a serverless GPU platform designed for AI workloads, offering sub-second cold starts, massive parallelism, and full observability. Built for developers who need high-performance inference, custom model serving, and scalable task execution without managing infrastructure.
Key Features
- Ultrafast GPU Inference: Deploy open-source LLMs behind autoscaling, OpenAI-compatible APIs with sub-second cold starts.
- Secure Sandboxes: Run any code in isolated, restorable environments with memory snapshots for instant branching and parallel execution.
- Task Queues: Scale workloads dynamically with queue-based autoscaling for large-scale batch processing and ETL.
- Multi-Cloud Support: Run workloads across AWS, GCP, or bare metal with unified billing and maximum cloud utilization.
- Developer Experience: Simplify deployment with a Python SDK—no Dockerfiles, YAML, or infrastructure management required.
- Observability: Full visibility into container utilization, performance metrics, and real-time streaming output.
- Use Cases: LLM inference, fine-tuning (LoRA/QLoRA), reinforcement learning, image generation (SDXL/Flux), and ComfyUI workflows.
Tech / Self-Hosting
Beam is a fully managed cloud service with no self-hosting option. It supports custom GPU configurations (e.g., H100, B200) and integrates with existing cloud accounts for bursting. The platform is optimized for AI-native workloads, offering memory snapshotting for rapid container restoration and global distribution across 30+ regions.