9 Best Open Source Azure Data Explorer Alternatives
A curated collection of the 9 best open source and self-hosted alternatives to Azure Data Explorer in 2026.
Looking for a free, privacy-friendly, or self-hosted replacement for Azure Data Explorer in 2026? The top open-source alternative is InfluxDB — Open-source time-series database for metrics and events.
Other highly rated open-source Azure Data Explorer alternatives include TDengine, QuestDB and Apache Druid.

Open-source time-series database for metrics and events
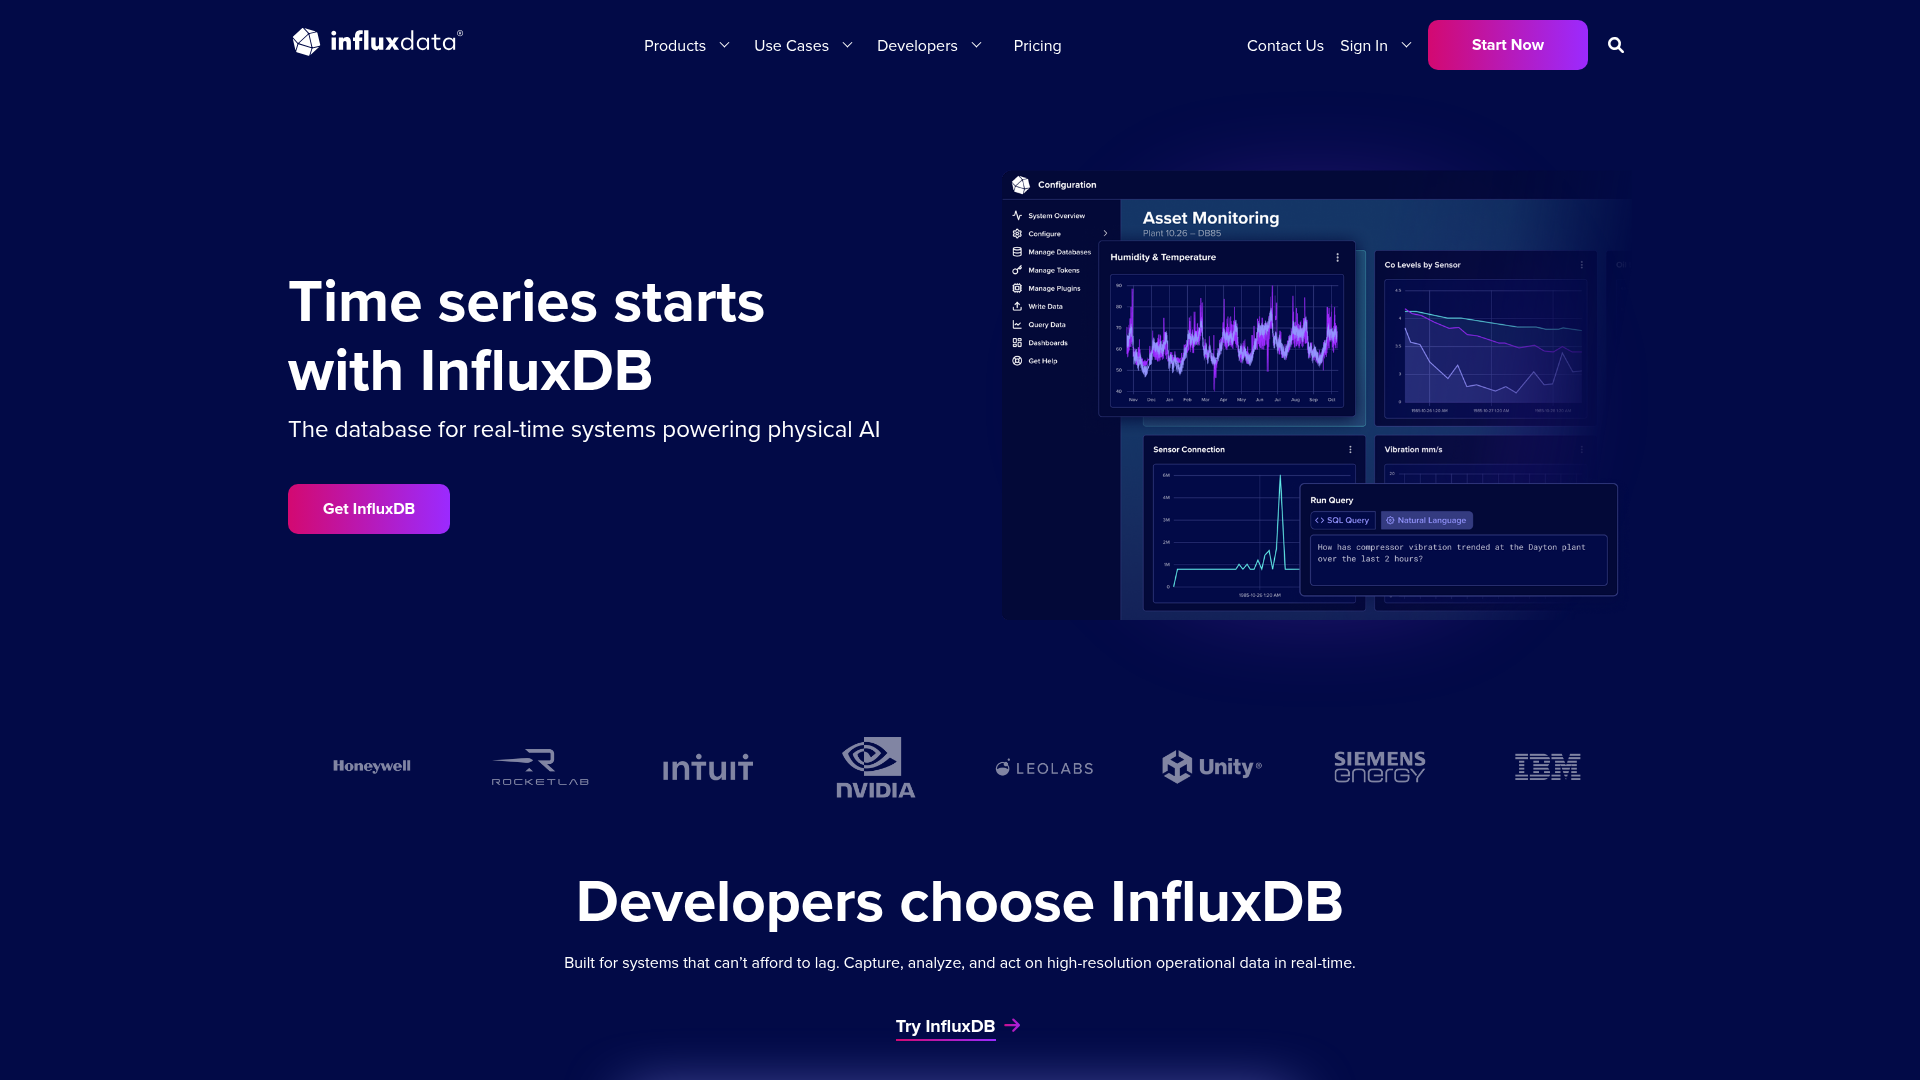
InfluxDB is a high-performance, open-source time-series database designed for handling metrics, events, and real-time analytics. It provides a scalable platform for collecting, storing, and querying time-stamped data efficiently. - High-performance data ingestion: Handles millions of data points per second with low latency. - Flexible query language: Powerful InfluxQL and Flux query languages for time-series analysis. - Self-managed & cloud options: Available as open-source (OSS) or enterprise-grade managed services. - Telegraf integration: Collects metrics from hundreds of sources with built-in plugins. - Real-time analytics: Enables instant insights with downsampling, continuous queries, and alerting. - Wide ecosystem: Supports integrations with Grafana, Prometheus, and other observability tools. - Multi-cloud & on-premises: Deployable across various environments with enterprise-grade security. - Time-series optimizations: Columnar storage and optimized compression for efficient data handling. InfluxDB is open-source (Apache 2.0 licensed) and can be self-hosted on Linux, macOS, or Windows. The OSS version supports single-node deployments, while enterprise editions offer clustering, high availability, and advanced features. Docker and Kubernetes deployments are officially supported. Documentation and community resources are available for setup and configuration.

Open-source time-series database for industrial data
TDengine is a high-performance, open-source time-series database designed for industrial data management. It combines time-series storage, asset modeling, and AI agents into a unified platform. - Time-Series Database: Optimized for high-speed data ingestion and storage of time-series data. - AI-Native Platform: Integrates AI applications directly into the data platform for advanced analytics. - Asset Modeling: Supports structured modeling of industrial assets and their relationships. - Visualization & Analytics: Built-in tools for data visualization and real-time analytics. - Scalability: Designed to handle large-scale industrial data workloads efficiently. - Free Tier: Offers a free forever tier for up to 5,000 tags. - Multi-Platform Support: Available as a self-hosted solution or via cloud deployment. TDengine is open-source and can be self-hosted on Linux, Windows, or macOS. It supports Docker for easy deployment and offers cloud-based solutions for managed services. The platform is designed for high availability and low-latency data processing, making it suitable for industrial applications.

Ultra-fast open-source time-series database
QuestDB is the open-source time-series database built for demanding workloads requiring ultra-low latency, high ingestion throughput, and multi-tier storage. Native support for Parquet and SQL ensures data portability and AI-readiness without vendor lock-in. - Ultra-low latency & high throughput: 10x faster ingest than competitors, purpose-built for latency-sensitive workloads - Multi-tier storage engine: Efficiently manages real-time and historical data with tiered architecture - Standard SQL support: Familiar SQL interface with time-series optimizations for developers and AI agents - Open data formats: Native Parquet and Iceberg support for portable, vendor-neutral data lakes - Horizontal scalability: Distributed architecture scales seamlessly across multiple availability zones - Production-ready resilience: High availability with multi-AZ support and enterprise-grade reliability - AI agent compatibility: Enables AI agents to query data using standard SQL they already know - Enterprise features: Advanced security, monitoring, and support for mission-critical deployments QuestDB is open-source (Apache 2.0 licensed) and can be self-hosted on any infrastructure. The database is optimized for modern cloud environments but works equally well on bare-metal servers. Official Docker images and Helm charts are available for easy deployment. The project provides comprehensive documentation for installation, configuration, and performance tuning.

High-performance real-time analytics database
Apache Druid is a high-performance, real-time analytics database designed for sub-second OLAP queries on massive datasets. It combines streaming and batch data processing with a distributed architecture that scales effortlessly while maintaining consistent performance. - Sub-second Queries: Execute OLAP queries in milliseconds on high-cardinality datasets with billions to trillions of rows without pre-caching. - High Concurrency: Supports 100s to 100,000s queries per second with consistent performance and minimal infrastructure overhead. - Real-time & Historical Insights: Native integration with Apache Kafka and Amazon Kinesis enables query-on-arrival at millions of events per second. - Interactive Query Engine: Utilizes scatter/gather for high-speed queries with data preloaded into memory or local storage. - Tiering & QoS: Configurable tiering with quality of service guarantees priority and avoids resource contention. - Optimized Data Format: Automatic columnarization, time-indexing, dictionary encoding, and type-aware compression. - Elastic Architecture: Loosely coupled components for ingestion, queries, and orchestration with deep storage layer for easy scaling. - True Stream Ingestion: Connector-free integration with streaming platforms for low-latency, high-scalability ingestion. - Non-stop Reliability: Continuous backup, automated recovery, and multi-node replication ensure high availability. - Schema Auto-Discovery: Automatically detects and updates column names and data types upon ingestion. - Flexible Joins Support: Supports join operations during ingestion and query-time execution. - SQL Support: Familiar SQL API for end-to-end data operations across ingestion, transformation, and querying. Apache Druid is an open-source project under the Apache Software Foundation. It can be self-hosted on any infrastructure and is designed for horizontal scaling. The project provides comprehensive documentation for deployment, configuration, and security best practices. Druid is proven in production at leading companies worldwide at massive scale. License: Apache License 2.0 Hosting: Self-hosted (cloud, on-premises, or hybrid) Documentation: Available at https://druid.apache.org/docs/latest/ Community: Active open-source community with Slack, meetups, and extensive documentation.
Cloud-native observability database unifying metrics, logs, and traces with sub-second queries, 50x cost reduction, and seamless OpenTelemetry integration.
Cloud-native observability database unifying metrics, logs, and traces with sub-second queries, 50x cost reduction, and seamless OpenTelemetry integration.

Open-source OLAP database for real-time analytics
Apache Pinot™ is an open-source distributed OLAP database designed for real-time analytics, serving both user-facing applications and AI agents with sub-second query latency on fresh data at petabyte scale. - Sub-Second Queries: Filter and aggregate petabyte datasets with P90 latencies in the tens of milliseconds, enabling interactive live results in UIs. - High Concurrency: Serve hundreds of thousands of concurrent queries per second for applications and AI agents. - Real-Time Streaming Ingestion: Ingest data in real-time from Apache Kafka, Apache Pulsar, AWS Kinesis, or batch sources like Hadoop, Spark, and AWS S3. - Upserts Support: Ingest the same record multiple times while only seeing the latest value at query time (production-tested since version 0.6). - Versatile Joins: Perform arbitrary fact/dimension and fact/fact joins on petabyte-scale datasets. - Rich Indexing Options: Pluggable indexes including timestamp, inverted, StarTree, Bloom filter, and range indexes for optimized query performance. - Multitenant Isolation: Enable customers to explore their own data in real time without pre-aggregation. - Embedded Analytics: Ship interactive dashboards inside products with support for 100K+ concurrent users querying live data. Apache Pinot is an open-source project hosted by the Apache Software Foundation. It can be self-hosted on any infrastructure, including cloud, on-premises, or hybrid environments. The project provides comprehensive documentation for deployment, scaling, and management, with support for containerized deployments via Docker and Kubernetes. Primary Use Cases: - User-facing analytics (dashboards, metrics APIs, customer-facing reports) - AI agent-facing analytics (RAG systems, decision engines, agentic observability) - Real-time decision-making platforms requiring sub-second latency Supported Data Sources: - Streaming: Kafka, Pulsar, AWS Kinesis - Batch: Hadoop, Spark, AWS S3, local files Deployment Options: - Self-hosted (bare metal, VMs, containers) - Cloud-agnostic (AWS, GCP, Azure, etc.) - Kubernetes-ready with Helm charts available Performance Characteristics: - Sub-second query latency on petabyte-scale data - Horizontal scalability through distributed architecture - High availability with automatic failover and recovery

Distributed search & analytics engine
Elasticsearch is a distributed, RESTful search and analytics engine designed for speed, horizontal scalability, reliability, and easy management. It enables fast and efficient data search, analysis, and visualization across large datasets. - Distributed & Scalable: Horizontally scalable architecture for handling petabytes of data. - Full-Text Search: Advanced search capabilities with relevance scoring and fuzzy matching. - Vector Database: Efficiently store and search vector embeddings for AI applications. - Real-Time Analytics: Process and analyze data in real-time with low latency. - Security & Observability: Built-in security features, log monitoring, and infrastructure insights. - AI Integration: Native support for AI-driven workflows, LLM observability, and automated threat detection. - Multi-Deployment Options: Available as self-managed, hosted cloud, or serverless. - Kibana Integration: Visualize and explore data with interactive dashboards and reports. - Self-Managed: Deploy on local servers, Kubernetes, or cloud infrastructure. - Elastic Cloud: Fully managed cloud service with serverless and hosted options. - Open Source: Core engine is open-source under the Elastic License.
Grafana unifies metrics, logs, traces, profiles, and business data into one OpenTelemetry-native platform with AI-assisted root cause analysis and adaptive cost controls.
Grafana unifies metrics, logs, traces, profiles, and business data into one OpenTelemetry-native platform with AI-assisted root cause analysis and adaptive cost controls.
Open-source transactional email platform
Plunk is an open-source, self-hostable email platform designed for transactional emails, marketing campaigns, and automated workflows. Built with privacy in mind, it offers transparent pricing, no contact limits, and full control over your email infrastructure. - Transactional & Marketing Emails: Send both transactional emails and marketing campaigns from a single platform. - Automated Workflows: Trigger workflows based on events sent from your code, with a visual canvas for full transparency. - Inbound Email Handling: Receive emails at your domain by adding an MX record, turning replies into contacts and triggering workflows. - Unlimited Contacts: Store unlimited contacts for free; pay only per email sent ($0.001 per email). - Self-Hosting & Open Source: Fully inspectable, forkable, and self-hostable under AGPL-3.0 license. - MCP Server Integration: Connect AI agents (Claude, Cursor) to manage emails via the Model Context Protocol. - Email Editor & SMTP: Visual editor for emails or direct HTML editing, plus SMTP support for existing clients. - Analytics & Segments: Track delivery, opens, clicks, and bounces per send, with dynamic segments that update in real-time. - License: AGPL-3.0 - Hosting: EU-based cloud or self-hosted via Docker Compose - GitHub Stars: 5,000+ - Setup Time: Under 5 minutes for domain configuration and first send - Exit Strategy: Full control via Docker Compose for seamless migration away from the cloud service.
About Azure Data Explorer
Azure Data Explorer is a fast and highly scalable data exploration service designed for querying and analyzing large volumes of log and telemetry data. It enables users to gain insights from structured, semi-structured, and unstructured data with minimal effort.
Key Features of Azure Data Explorer
- High-performance querying: Optimized for fast data exploration and analysis.
- Scalability: Handles massive datasets with ease.
- Log and telemetry focus: Specialized for log analytics and monitoring.
- Integration with Azure ecosystem: Seamlessly works with other Azure services.
- Real-time analytics: Supports real-time data ingestion and analysis.
- Kusto Query Language (KQL): Uses a powerful query language for data analysis.
- Cost-effective: Pay-as-you-go pricing model.
Tech / Self-Hosting
Azure Data Explorer is a fully managed cloud service provided by Microsoft Azure. It is not available for self-hosting as it operates as a SaaS offering within the Azure cloud platform.