10 Best Open Source Amazon Timestream Alternatives
A curated collection of the 10 best open source and self-hosted alternatives to Amazon Timestream in 2026.
Looking for a free, privacy-friendly, or self-hosted replacement for Amazon Timestream in 2026? The top open-source alternative is InfluxDB — Open-source time-series database for metrics and events.
Other highly rated open-source Amazon Timestream alternatives include TDengine, TimescaleDb and VictoriaMetrics.

Open-source time-series database for metrics and events
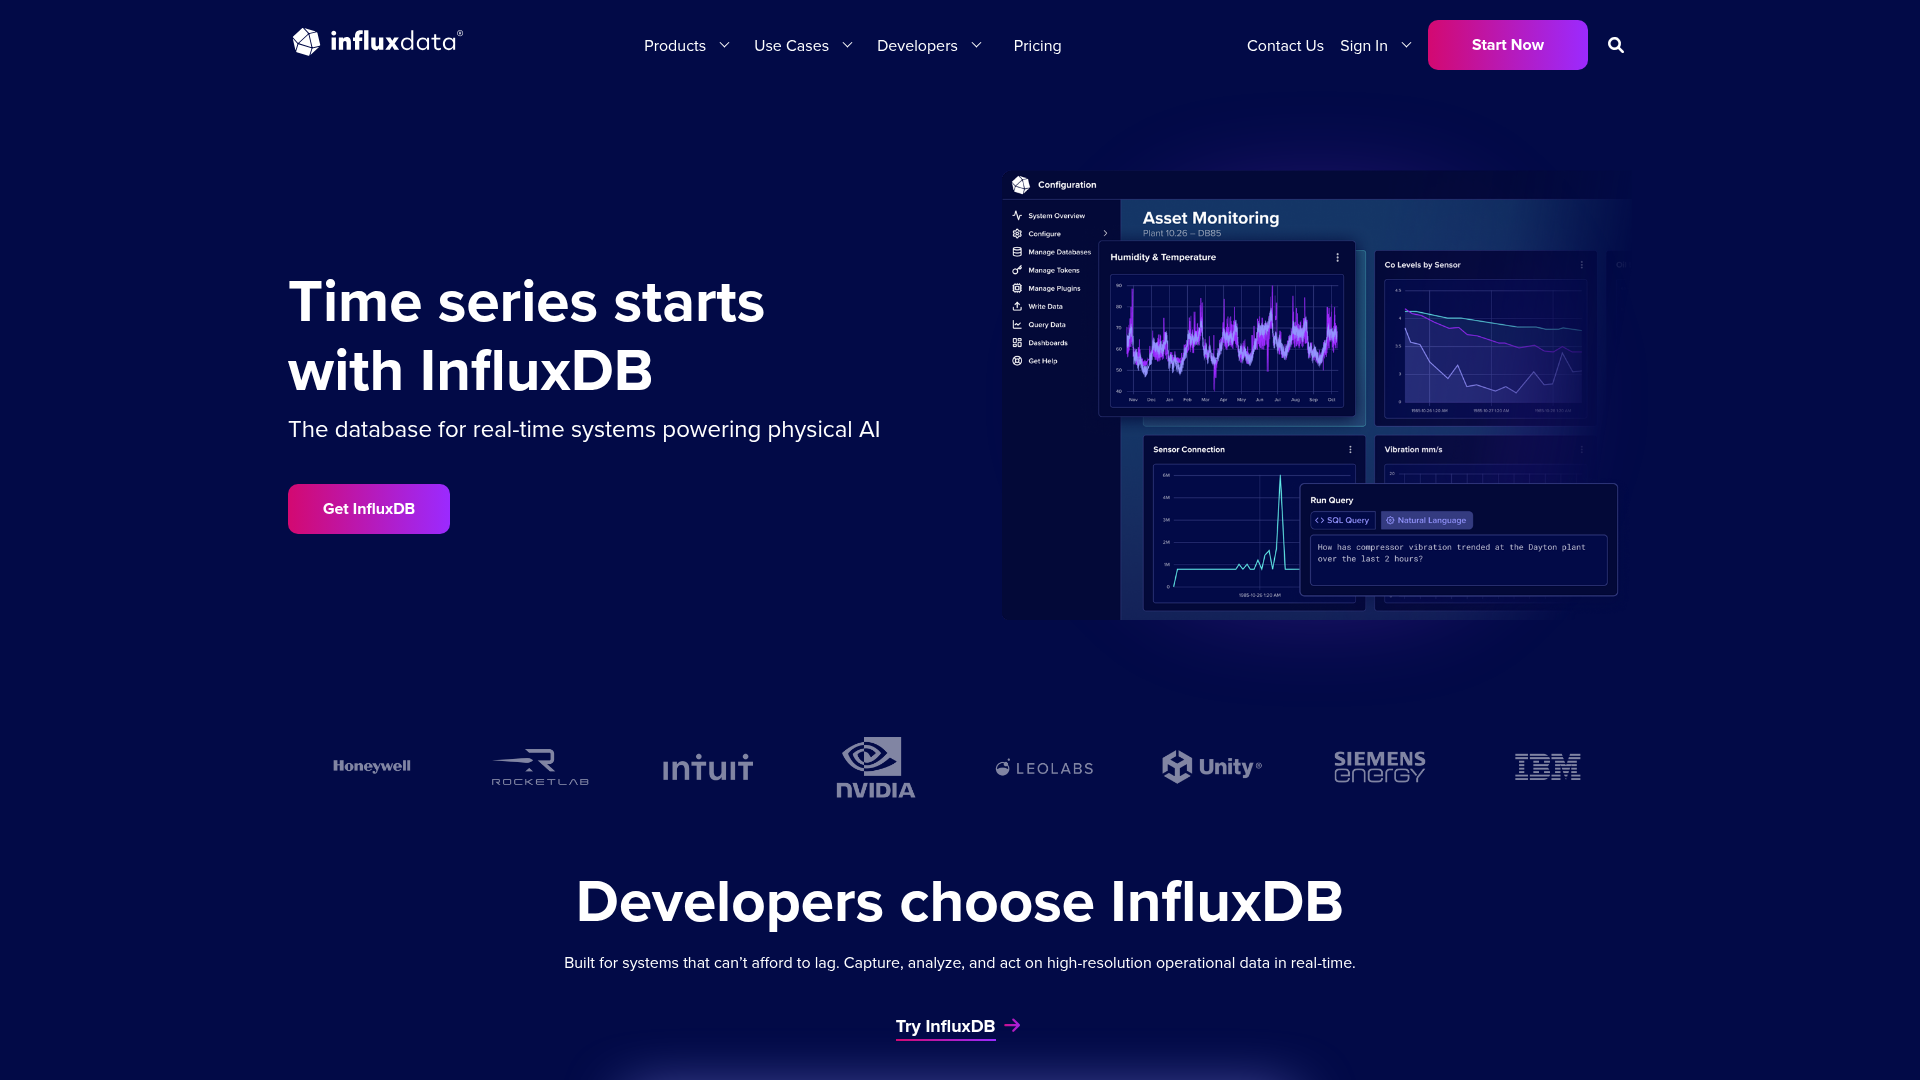
InfluxDB is a high-performance, open-source time-series database designed for handling metrics, events, and real-time analytics. It provides a scalable platform for collecting, storing, and querying time-stamped data efficiently. - High-performance data ingestion: Handles millions of data points per second with low latency. - Flexible query language: Powerful InfluxQL and Flux query languages for time-series analysis. - Self-managed & cloud options: Available as open-source (OSS) or enterprise-grade managed services. - Telegraf integration: Collects metrics from hundreds of sources with built-in plugins. - Real-time analytics: Enables instant insights with downsampling, continuous queries, and alerting. - Wide ecosystem: Supports integrations with Grafana, Prometheus, and other observability tools. - Multi-cloud & on-premises: Deployable across various environments with enterprise-grade security. - Time-series optimizations: Columnar storage and optimized compression for efficient data handling. InfluxDB is open-source (Apache 2.0 licensed) and can be self-hosted on Linux, macOS, or Windows. The OSS version supports single-node deployments, while enterprise editions offer clustering, high availability, and advanced features. Docker and Kubernetes deployments are officially supported. Documentation and community resources are available for setup and configuration.

Open-source time-series database for industrial data
TDengine is a high-performance, open-source time-series database designed for industrial data management. It combines time-series storage, asset modeling, and AI agents into a unified platform. - Time-Series Database: Optimized for high-speed data ingestion and storage of time-series data. - AI-Native Platform: Integrates AI applications directly into the data platform for advanced analytics. - Asset Modeling: Supports structured modeling of industrial assets and their relationships. - Visualization & Analytics: Built-in tools for data visualization and real-time analytics. - Scalability: Designed to handle large-scale industrial data workloads efficiently. - Free Tier: Offers a free forever tier for up to 5,000 tags. - Multi-Platform Support: Available as a self-hosted solution or via cloud deployment. TDengine is open-source and can be self-hosted on Linux, Windows, or macOS. It supports Docker for easy deployment and offers cloud-based solutions for managed services. The platform is designed for high availability and low-latency data processing, making it suitable for industrial applications.

Time-series database built on PostgreSQL
TimescaleDB is an open-source time-series database built on PostgreSQL, designed for high-performance real-time analytics on time-series data. It combines the reliability of PostgreSQL with specialized time-series optimizations, making it ideal for applications requiring fast ingest, efficient storage, and complex queries. - 100% PostgreSQL Compatible: Runs as a PostgreSQL extension, leveraging existing PostgreSQL tools, drivers, and ecosystem. - Automatic Partitioning: Hypertables automatically partition data by time or ID for fast ingest and predictable queries with partition skipping. - Hybrid Row/Columnar Storage: Recent data stays in row format for writes, while older data converts to columnar for fast analytical scans. - Up to 95% Compression: Reduces storage costs significantly while keeping years of history queryable online using delta, dictionary, and RLE encodings. - 200+ Native SQL Functions: Hyperfunctions simplify advanced time-series analysis with functions for time-weighted averages, interpolation, and partial aggregations. - Incremental Materialized Views: Continuous aggregates refresh rollups incrementally, keeping dashboards instant with parallelized batched refreshes. - Automated Management: Built-in job scheduler with retries, configurable retention policies, and full auditability for columnstore, retention, and aggregate refresh. - Real-time Analytics: Queryable real-time analytics at production scale with compressed history. - Open Source: Available under the Apache 2.0 license with 23,000+ GitHub stars. - Self-Hosted Options: Deployable on-premises, in private clouds, or via cloud platforms like Tiger Cloud. - Enterprise Features: TimescaleDB Enterprise offers additional capabilities for on-prem, edge, and private cloud deployments. - Cloud Platform: Tiger Cloud provides a robust elastic cloud platform for startups and enterprises. - Documentation: Comprehensive docs available at https://www.tigerdata.com/docs.

Fast, scalable observability database for metrics, logs and traces
VictoriaMetrics is a fast, cost-effective, and scalable monitoring solution for metrics, logs, and traces. It provides high-performance time-series databases designed for observability at scale. - High Performance: Optimized for fast data ingestion and query processing, handling millions of metrics per second. - Scalability: Supports horizontal scaling for large-scale deployments with minimal overhead. - Multi-Data Support: Includes VictoriaMetrics (metrics), VictoriaLogs (logs), and VictoriaTraces (traces) for comprehensive observability. - Open Source Core: Core components are open-source with enterprise-grade features available in the commercial version. - Compatibility: Compatible with Prometheus, Grafana, and other observability tools. - Enterprise Features: Offers advanced features like anomaly detection, long-term storage, and high availability. - Cloud & Self-Hosted: Available as a managed cloud service or self-hosted solution. - Cost-Effective: Reduces storage and compute costs compared to traditional monitoring solutions. VictoriaMetrics can be deployed on-premises or in the cloud. It supports Kubernetes, Docker, and bare-metal installations. The open-source version is available under the Apache 2.0 license, while enterprise features require a commercial license. Documentation and community support are provided for self-hosting.

Ultra-fast open-source time-series database
QuestDB is the open-source time-series database built for demanding workloads requiring ultra-low latency, high ingestion throughput, and multi-tier storage. Native support for Parquet and SQL ensures data portability and AI-readiness without vendor lock-in. - Ultra-low latency & high throughput: 10x faster ingest than competitors, purpose-built for latency-sensitive workloads - Multi-tier storage engine: Efficiently manages real-time and historical data with tiered architecture - Standard SQL support: Familiar SQL interface with time-series optimizations for developers and AI agents - Open data formats: Native Parquet and Iceberg support for portable, vendor-neutral data lakes - Horizontal scalability: Distributed architecture scales seamlessly across multiple availability zones - Production-ready resilience: High availability with multi-AZ support and enterprise-grade reliability - AI agent compatibility: Enables AI agents to query data using standard SQL they already know - Enterprise features: Advanced security, monitoring, and support for mission-critical deployments QuestDB is open-source (Apache 2.0 licensed) and can be self-hosted on any infrastructure. The database is optimized for modern cloud environments but works equally well on bare-metal servers. Official Docker images and Helm charts are available for easy deployment. The project provides comprehensive documentation for installation, configuration, and performance tuning.

Industrial IoT time-series database for edge-cloud data
Apache IoTDB is an industrial IoT time-series database management system that adopts a lightweight architecture with edge-cloud collaboration, supporting integrated collection, storage, management, and analysis of IoT time-series data. It features multi-protocol compatibility, ultra-high compression ratio, high-throughput read/write capabilities, industrial-grade stability, and minimal maintenance requirements. Download Quick Start - High-throughput read/write: Supports millions of low-power IoT devices with lightning-fast data retrieval and storage. - Efficient directory structure: Organizes complex IoT data structures with fuzzy searching for large-scale time-series datasets. - Rich query semantics: Enables time alignment across devices, in-field computations, and aggregation functions in time dimensions. - Low hardware cost: Achieves high compression ratios (e.g., <$0.23 to store 1GB of data on hard disk). - Flexible deployment: Offers one-click cloud installation, desktop terminal tools, and cloud-to-on-premise synchronization. - Open-source ecosystem integration: Compatible with Hadoop, Spark, Flink, and Grafana for advanced analytics and visualization. Apache IoTDB is an open-source project under the Apache Software Foundation, licensed under the Apache License 2.0. It can be self-hosted on any infrastructure and supports various deployment models including cloud, on-premise, and hybrid environments. The project provides comprehensive documentation, community support, and enterprise-grade stability for production use. GitHub Repository: https://github.com/apache/iotdb Primary Website: https://iotdb.apache.org

Open-source OLAP database for real-time analytics
Apache Pinot™ is an open-source distributed OLAP database designed for real-time analytics, serving both user-facing applications and AI agents with sub-second query latency on fresh data at petabyte scale. - Sub-Second Queries: Filter and aggregate petabyte datasets with P90 latencies in the tens of milliseconds, enabling interactive live results in UIs. - High Concurrency: Serve hundreds of thousands of concurrent queries per second for applications and AI agents. - Real-Time Streaming Ingestion: Ingest data in real-time from Apache Kafka, Apache Pulsar, AWS Kinesis, or batch sources like Hadoop, Spark, and AWS S3. - Upserts Support: Ingest the same record multiple times while only seeing the latest value at query time (production-tested since version 0.6). - Versatile Joins: Perform arbitrary fact/dimension and fact/fact joins on petabyte-scale datasets. - Rich Indexing Options: Pluggable indexes including timestamp, inverted, StarTree, Bloom filter, and range indexes for optimized query performance. - Multitenant Isolation: Enable customers to explore their own data in real time without pre-aggregation. - Embedded Analytics: Ship interactive dashboards inside products with support for 100K+ concurrent users querying live data. Apache Pinot is an open-source project hosted by the Apache Software Foundation. It can be self-hosted on any infrastructure, including cloud, on-premises, or hybrid environments. The project provides comprehensive documentation for deployment, scaling, and management, with support for containerized deployments via Docker and Kubernetes. Primary Use Cases: - User-facing analytics (dashboards, metrics APIs, customer-facing reports) - AI agent-facing analytics (RAG systems, decision engines, agentic observability) - Real-time decision-making platforms requiring sub-second latency Supported Data Sources: - Streaming: Kafka, Pulsar, AWS Kinesis - Batch: Hadoop, Spark, AWS S3, local files Deployment Options: - Self-hosted (bare metal, VMs, containers) - Cloud-agnostic (AWS, GCP, Azure, etc.) - Kubernetes-ready with Helm charts available Performance Characteristics: - Sub-second query latency on petabyte-scale data - Horizontal scalability through distributed architecture - High availability with automatic failover and recovery
Distributed SQL database designed for high-speed ingestion and complex queries on massive datasets, ideal for IoT and time-series data.
Distributed SQL database designed for high-speed ingestion and complex queries on massive datasets, ideal for IoT and time-series data.
Open-source monitoring & time series database
Prometheus is an open-source monitoring system and time series database designed for cloud-native environments. It provides a flexible dimensional data model, a powerful PromQL query language, and efficient alerting mechanisms. - Dimensional data model: Identifies time series by metric names and key-value pairs for flexible data organization. - PromQL query language: Enables powerful querying, correlation, and transformation of time series data for visualizations and alerts. - Precise alerting: Uses Alertmanager to handle notifications and silencing based on PromQL rules. - Simple operation: Operates independently with local storage, deployable as statically linked binaries across environments. - Instrumentation libraries: Offers official and community-contributed libraries for metrics instrumentation in major languages. - Ubiquitous integrations: Includes hundreds of official and community integrations for extracting metrics from existing systems. - Cloud-native integration: Works seamlessly with Kubernetes and other cloud/container managers for continuous service discovery and monitoring. - Open governance: A CNCF graduated project with 100% open-source components under the Apache 2 License. Prometheus is 100% open-source and self-hostable, with all components available under the Apache 2 License. It is developed in Go and designed for easy deployment across various environments, including Kubernetes and cloud infrastructures. The system operates independently with local storage, ensuring minimal external dependencies.

Unified chat & AI SDK for web, iOS & Android
Ethora provides a unified SDK to integrate real-time chat, AI agents, and interactive workflows into web, iOS, and Android applications. Designed for developers and businesses, it supports self-hosting for full data ownership and compliance with standards like HIPAA, SOC 2, and GDPR. - Cross-Platform SDK: Compatible with web, iOS, Android, React.js, React Native, and legacy systems. - AI Agent Builder: No-code tool to create AI agents with RAG capabilities by crawling websites and indexing documents. - Self-Hosting: Deploy on AWS, your own cloud, or on-premises for complete data control. - Vertical-Specific Solutions: Pre-configured SDKs for finance, healthcare, gaming, education, and more. - Voice & Video Chat: Real-time voice and audio rooms for enhanced user engagement. - Embeddable Widgets: Drop-in chat and AI agent widgets for any website or portal. - Compliance Ready: HIPAA, SOC 2, and GDPR compliant for sensitive industries. - Document Indexing: Turn unstructured documents into AI knowledge bases for RAG applications. Ethora is open-source and can be self-hosted on AWS, private clouds, or on-premises. The platform supports integration with existing infrastructure and provides tools for data privacy and security compliance. Documentation and support are available for developers to customize and extend functionality.
About Amazon Timestream
Amazon Timestream is a fast, scalable, serverless time series database service designed for Internet of Things (IoT) and operational applications. It helps you efficiently store and analyze time series data with built-in analytics capabilities.
Key Features of Amazon Timestream
- Serverless architecture – Automatically scales to handle millions of requests per second without manual provisioning.
- Time series optimized – Built specifically for time-stamped data, reducing storage costs by up to 90% compared to traditional databases.
- Built-in analytics – Supports time-series-specific functions for filtering, aggregation, and downsampling.
- Query performance – Delivers fast query responses with optimized storage and indexing.
- Integration with AWS ecosystem – Seamlessly connects with Amazon CloudWatch, AWS Lambda, and other AWS services.
- Automatic tiering – Moves older data to cost-effective storage tiers while keeping recent data readily accessible.
- Security & compliance – Encrypted at rest and in transit, with support for AWS IAM and VPC endpoints.
Tech / Self-Hosting
Amazon Timestream is a fully managed AWS service and does not support self-hosting. It is hosted on AWS infrastructure and requires an AWS account for access.